Neuron.
The offensive security execution platform.
Plan, execute, review and deliver every engagement in one system that you run. This page covers how it works, what it runs on and what it connects to. Feature-by-feature detail lives on neuron.ws.
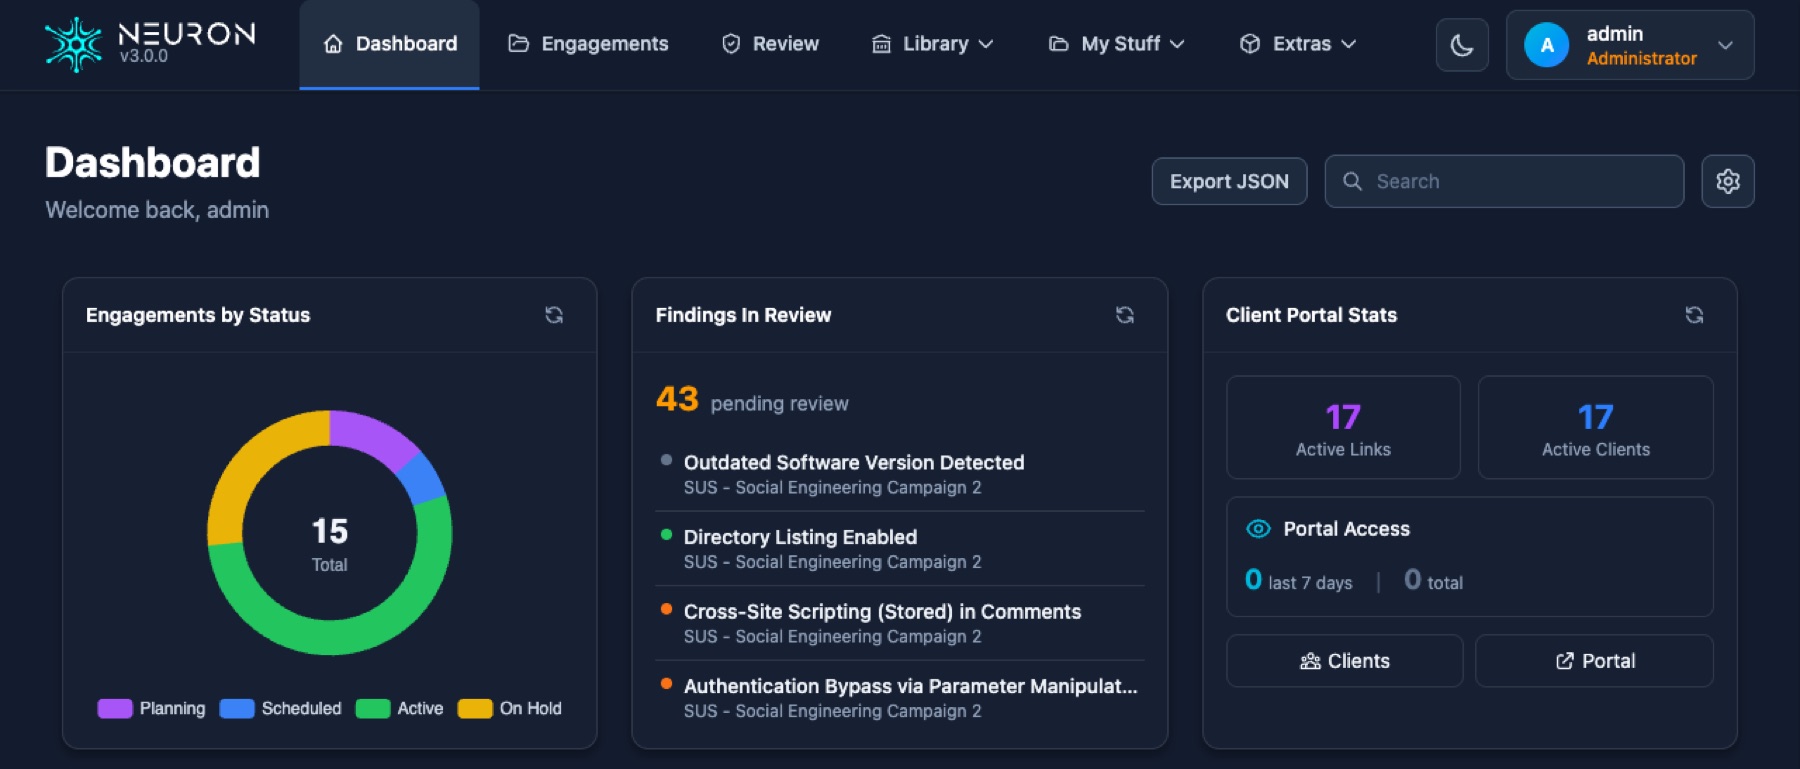
Five stages.
Real states, not slideware.
Each stage below shows the states Neuron actually records. An engagement moves through all of them in one system, from the first scoping call to the final retest.
- 01
Scope
Planning→Scheduled→Active→Completed
An engagement starts from a saved template and takes one or more assessments from a catalogue of 22, grouped as applications, infrastructure, adversary simulation and devices. Each assessment brings its own fields, methodology mapping and finding ID prefix. Testers are allocated on a shared Gantt schedule.
- OWASP, MITRE ATT&CK and ATLAS, CIS and DISA STIG mappings
- Lead, member and observer roles
- Retests scheduled beside new work
- 02
Test
New→In review→Confirmed→Promoted
Around twenty importers feed hosts, services, web applications and a scan issue triage queue. Playbooks track coverage step by step, and credentials, people and events are recorded on the engagement as the work happens.
- Any import can be rolled back
- Enrichment from NVD, CISA KEV and ExploitDB
- Per-engagement Active Directory and Entra ID graphs
- 03
Review
Draft→In review→Pending approval→Approved
Findings, briefs and library variants go through review inside the engagement. The reviewer and approver must be different people, nobody approves their own work, and approval stays blocked while any tracked change or comment is unresolved.
- Attributed track changes
- Review queue aging and overdue digests
- Approved content becomes read-only
- 04
Deliver
Draft→Published→Superseded→Withdrawn
Reports render from your own Word templates, with PDF, Excel and Markdown from the same data. Deliverables go out through the Delivery Portal, where Controlled Release requires a signed acknowledgement before download and every PDF is watermarked with its recipient.
- Partial and full release of findings
- Briefs with a version per language
- Delivery Portal activity log per client
- 05
Retest
Planned→In progress→Ready for approval→Completed
Each retest round records an outcome per finding: resolved, partially resolved, not resolved, risk accepted, or no retest performed. Verdicts can require a co-signature, and a round locks once it is ready for approval.
- Clients request retests from the portal
- Per-round approver and audit trail
Four parts.
All of them yours.
Neuron Core is a single binary for Linux on x64 or arm64, behind your reverse proxy, with PostgreSQL 14 or later and a Reporting Engine in Docker. Neuron AI and the Delivery Portal are optional and can each run on their own host.
Install guides cover your own hardware, AWS, Azure, Google Cloud, Oracle Cloud and fully air-gapped networks.
| Tier | vCPU | RAM | Disk |
|---|---|---|---|
| Small, 1 to 10 users | 2 | 8 GB | 50 GB |
| Medium, 10 to 50 users | 4 | 16 GB | 100 GB |
| Large, over 50 users | 8 | 32 GB | 200 GB |
Ubuntu 22.04 or later recommended. Neuron AI is sized separately, or added to a combined server.
AI that runs
on your hardware.
Neuron AI is a separate service that runs local models on your own GPU or CPU, on the Core host or its own. It makes no outbound calls during inference, and no prompt, finding or piece of evidence is sent to a third-party model provider.
It drafts findings, briefs and library variants, and each AI function can be routed to a different model. Every draft goes through the same review and approval as one a person wrote.
Official models only
Models are delivered as files and run inside your network. A model without the official Neuron marker is refused.
Air-gap ready
Models and AI updates install from transferred files, and an update installs only if it carries Neuron's signature.
Accountable
An AI activity log records each generation, and a person approves what ships. We do not train on customer data.
| Model | Size on disk | 8 vCPU, CPU only | NVIDIA L4 24 GB |
|---|---|---|---|
| Compact | 1.9 GB | 19.5 tok/s, 26 s | 93 tok/s, 3 s |
| Standard | 3.3 GB | 8.0 tok/s, 64 s | 53 tok/s, 10 s |
| Flagship | 7.0 GB | 4.5 tok/s, 113 s | 32 tok/s, 16 s |
Steady-state tokens per second, and time to draft a typical report section, measured on AWS m7i.2xlarge and g6.xlarge instances. A 24 GB GPU runs any bundled model. One model is resident at a time.
Fits the tools
you already run.
ServiceNow
Routing rules push approved findings automatically, with evidence images, field mappings and your own severity names. Pushes queue, retry and keep an exportable history.
REST API
The platform is available over /api/v3, with OpenAPI documentation in the Help Center and tokens that can be limited to specific engagements.
Burp Suite extension
Send results from Burp Suite into the engagement live, alongside file imports from Burp and OWASP ZAP. Web applications, endpoints and parameters become assets.
- Nmap
- Masscan
- Nessus
- Nexpose
- Qualys
- OpenVAS
- Nuclei
- Nikto
- Acunetix
- Invicti
- Burp Suite
- OWASP ZAP
- OpenAPI
- Shodan
- Censys
- PCAP
- Prowler
- ScoutSuite
- MobSF
- SharpHound
- AzureHound
- Target and URL lists
Start with Core.
Add what you need.
Neuron Core
Engagements, scheduling, imports, playbooks, the findings library, QA, reporting, retests, SSO and the REST API.
Neuron AI
Local models that draft findings, briefs and library variants on your own GPU or CPU.
Directory
Per-engagement Active Directory and Entra ID attack graphs with edge provenance and path confidence.
Delivery Portal
A separate portal where clients see released findings and deliverables, sign acknowledgements and request retests.
Workflow Integrations
ServiceNow push with routing rules, a background queue and push history.
File Shares
Team file storage on your server, with revisions, previews, content search and zip downloads.
Custom Branding
Your name and look on the Delivery Portal and its sign-in pages.
Neuron 3.0 shipped in December 2025, and 29 releases followed by the end of September 2026. See the full record.
See it on your own terms.
We will show you Neuron sized for your team, on the deployment you would actually run, with or without the AI.